Data Sovereignty in Manufacturing: Putting Data Control into Practice
This article shows how true data control comes about: through local infrastructure, clear access rules, and full traceability of all AI and data flows.
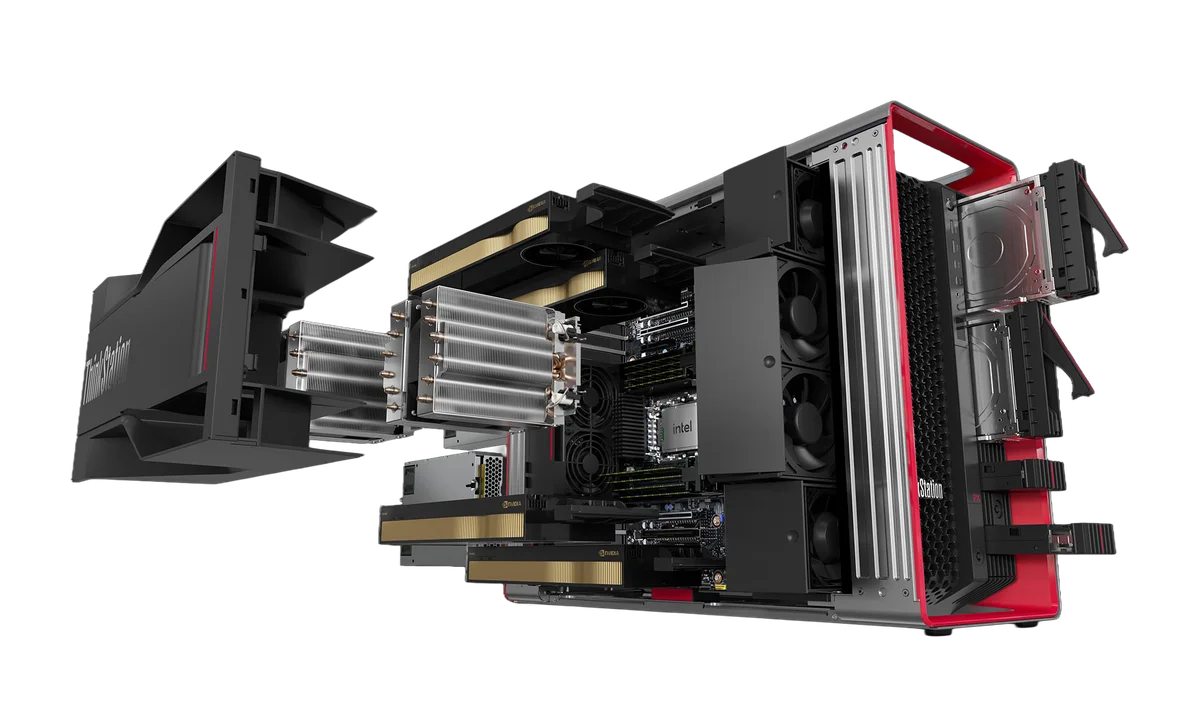
Data control is not a setting in a cloud dashboard. It is an architecture decision. Anyone who sends machine data, quality records, and process parameters to external services – even if only for analysis – gives up part of their control. This affects not only data protection but also operational security: what happens to your production data if the vendor changes its terms, gets acquired, or simply goes offline?
What true data control requires in practice
- Physical control: The data resides on systems in your own facility – not in a data center you have never seen.
- Structured data management: A central data lake with clear data paths, access rules, and quality criteria – as the foundation for every AI use case.
- Traceability: Every data access, every model query, and every result is documented and auditable – without a vendor ticket.
- Independence from the vendor ecosystem: No proprietary formats, no lock-in, no data loss when switching vendors.
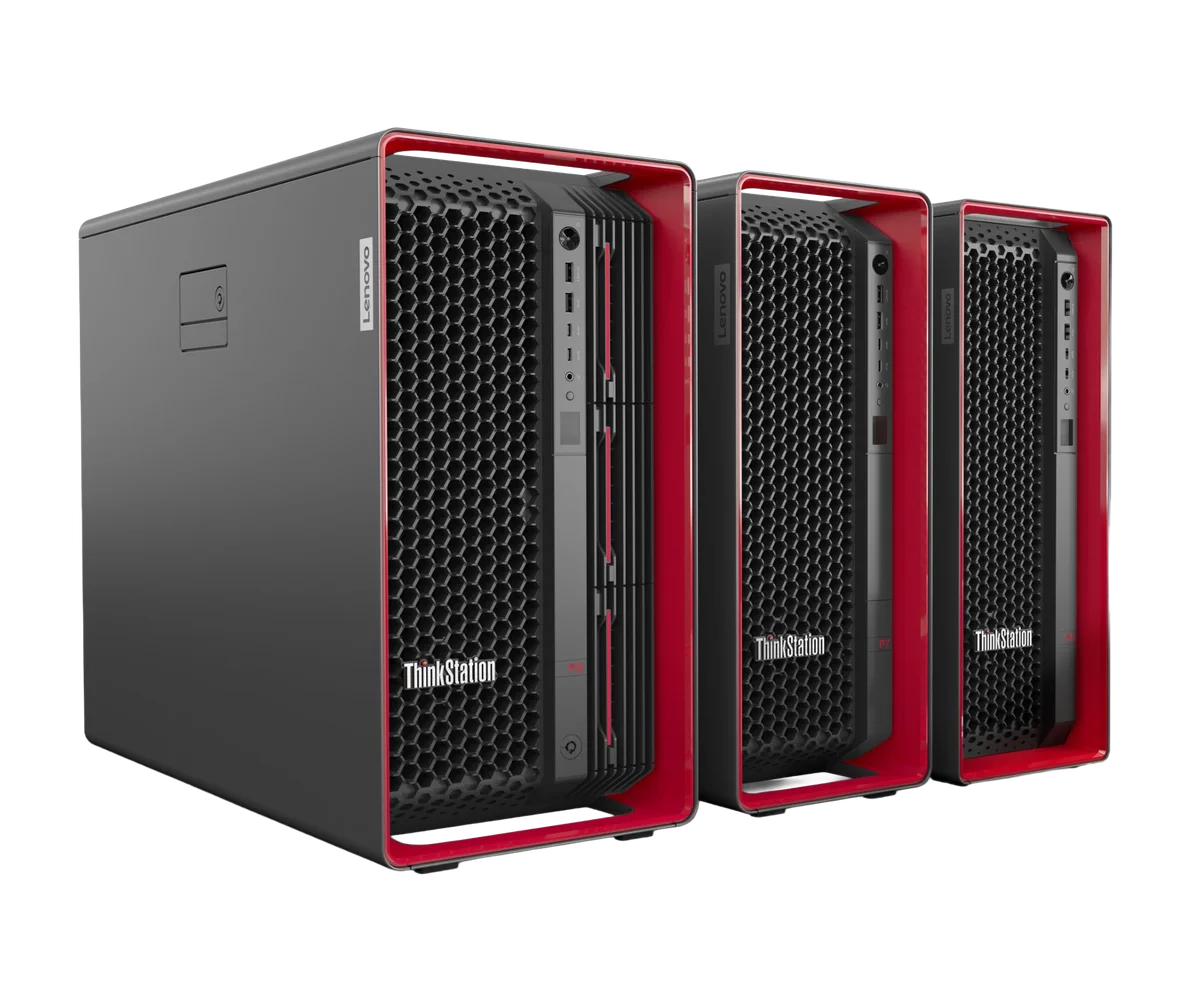
OPAIRS: Data lake and AI inference under one roof
The OPAIRS system integrates an industrial data lake directly with the SLM inference layer – all local, all under your control. Production data does not flow through third-party APIs. Models run locally. Results land directly in the connected BI dashboard. Own your Data again – that is not a core message, it is a technical fact.
Governance is the organizational framework that makes this technical foundation usable: clear roles, defined access boundaries, measurable quality criteria. With OPAIRS, you build both at the same time – infrastructure and governance foundation – instead of one after the other.
More insights
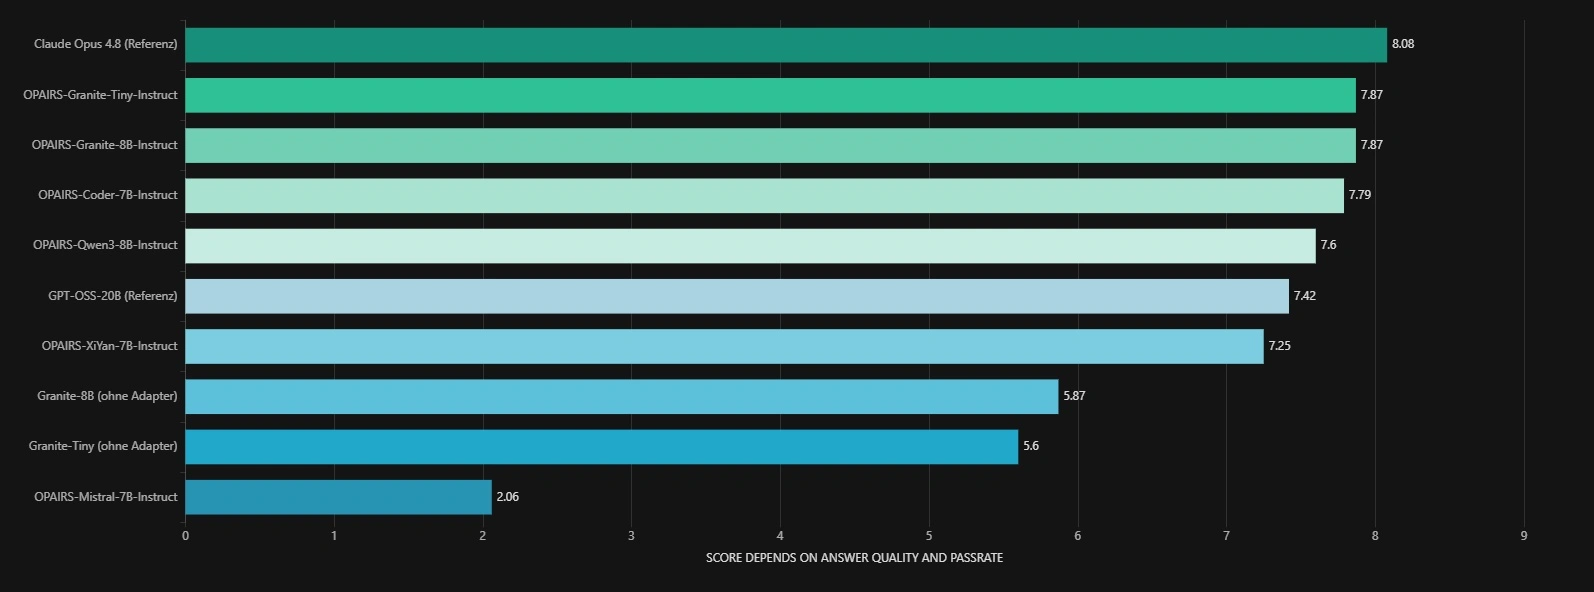
OPAIRS SQL Agent: Comparing Six LoRA Adapters for Industrial Databases
Six LoRA adapters, a 26-question catalog spanning PostgreSQL, T-SQL and Apache Iceberg databases, two external reference models: OPAIRS has systematically evaluated its SQL agent. Two Granite adapters lead the field. For production use, however, the deciding factors are not only answer quality but also speed, memory footprint, concurrency and the available context from ERP, MES, PLM and other industrial systems.
Read article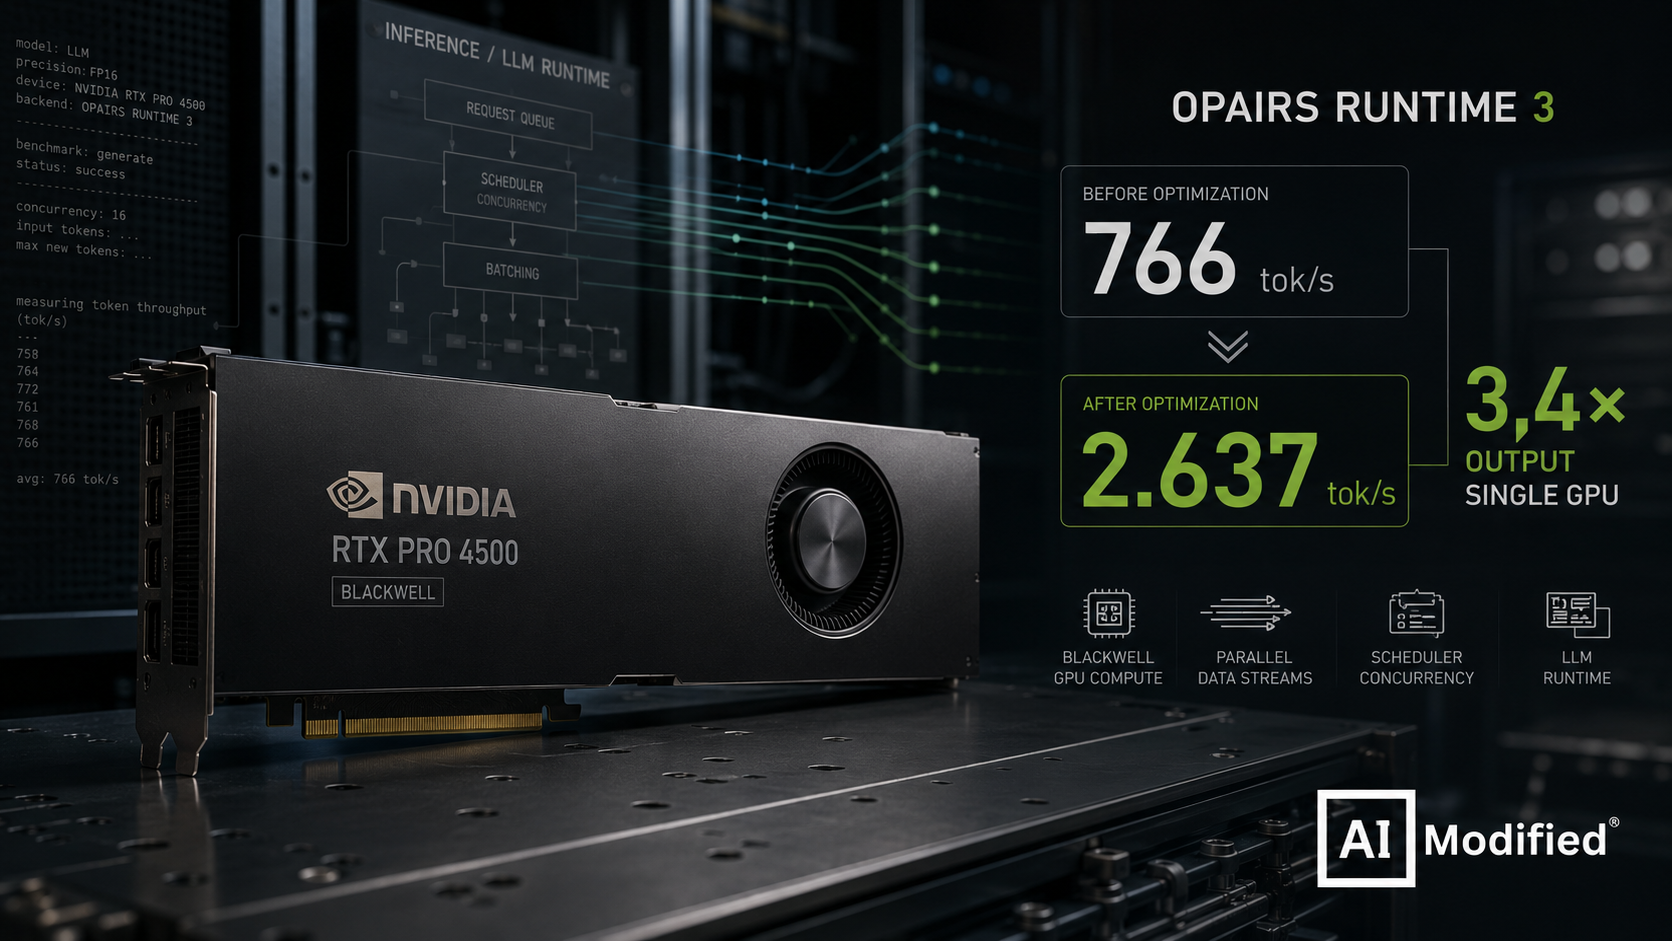
RTX PRO 4500 Blackwell: 3.4x LLM Throughput Through Runtime Optimization
Same GPU, same main model, up to 3.4x the output: OPAIRS Runtime 3 raises the throughput of GPT-OSS-20B on the RTX PRO 4500 Blackwell to up to 2,637 tokens/s. At the same time, the tests show why Qwen3.8-27B will not take over the production stack for now.
Read article