OPAIRS Joins the NVIDIA Inception Program
GPU-accelerated LLM inference on-premise: what NVIDIA Inception means for the OPAIRS stack, and why sovereign AI and high-performance hardware must go hand in hand.

What Is the NVIDIA Inception Program?
The NVIDIA Inception program is a free support program for technology startups that assists companies at every stage of their development. Members gain access to the latest NVIDIA developer resources and training offerings, receive exclusive terms on NVIDIA hardware and software, and are connected to NVIDIA's global venture capital network. Thousands of AI startups worldwide are part of this ecosystem.
GPU Power – Local, Dedicated, Under Your Control
OPAIRS is designed as an on-premise system: all AI workloads run on dedicated hardware directly at the customer site – no shared cloud resources, no external API calls, no vendor lock-in. NVIDIA GPUs accelerate local LLM inference via vLLM, so that industrial use cases such as prescriptive maintenance, knowledge management, and process optimization can be processed in real time. Membership in the NVIDIA Inception program strengthens this approach: OPAIRS thereby gains direct access to the latest optimization tools and hardware developments – before they are available on the market.
NVIDIA Technologies in the OPAIRS Stack
OPAIRS already relies today on Gemma, Nemotron, and Qwen language models, which are fine-tuned via QLoRA on industrial domain data directly on EuroHPC GPU infrastructure (Leonardo BOOSTER, Bologna) and then deployed locally. For inference, vLLM with CUDA acceleration is used. As we continue development, we are evaluating NVIDIA NeMo Guardrails for controlled model outputs in safety-critical industrial processes, NVIDIA NeMo Customizer for domain-specific fine-tuning directly on the appliance, and the NeMo Agent Toolkit for orchestrating multiple specialized AI agents along manufacturing processes.

Sovereign AI Needs High-Performance Hardware
The OPAIRS approach combines two requirements that are often perceived as contradictory in industry: full data sovereignty on the one hand and state-of-the-art AI performance on the other. Those who outsource AI to the cloud get compute power, but lose control over data, models, traceability, and decision paths. Those who build everything themselves have control but often lack the necessary infrastructure. OPAIRS delivers both: a preconfigured, certification-ready on-premise appliance with NVIDIA GPU acceleration, operated and maintained at the customer site, without cloud dependency.
What Membership Means for OPAIRS Customers
- Early access to new NVIDIA developer tools and hardware generations, and OPAIRS customers benefit directly through system updates.
- Validated integration: close collaboration with NVIDIA ensures that the OPAIRS stack is optimally aligned with current GPU architectures.
- Access to the NVIDIA partner network – relevant for joint projects, hardware procurement, and funding applications.
- Visibility as a vetted AI startup: NVIDIA actively recommends Inception members to customers and partners.
OPAIRS Systems is a member of the NVIDIA Inception program. We are delighted to be admitted to this global ecosystem and see it as a confirmation of our technical approach: GPU-accelerated, sovereign AI infrastructure for manufacturing companies in the DACH region – on-premise, air-gap capable, and EU AI Act-ready.
More insights
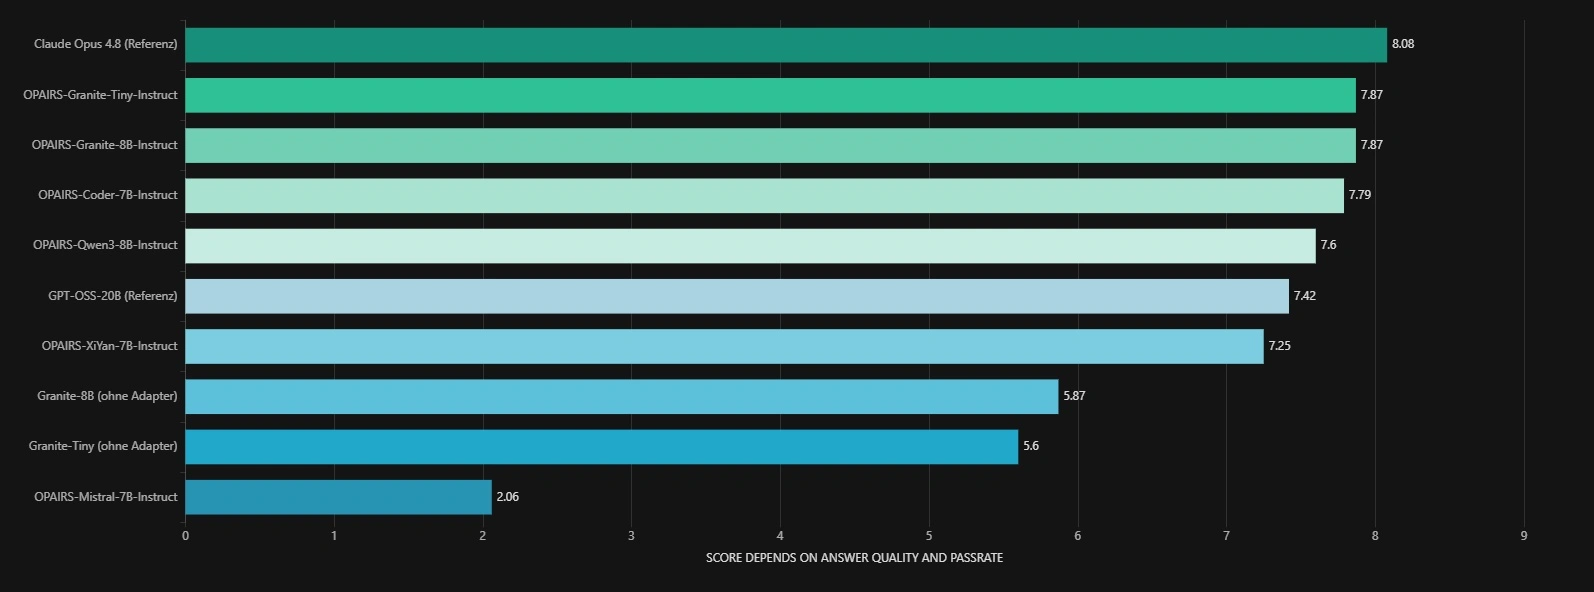
OPAIRS SQL Agent: Comparing Six LoRA Adapters for Industrial Databases
Six LoRA adapters, a 26-question catalog spanning PostgreSQL, T-SQL and Apache Iceberg databases, two external reference models: OPAIRS has systematically evaluated its SQL agent. Two Granite adapters lead the field. For production use, however, the deciding factors are not only answer quality but also speed, memory footprint, concurrency and the available context from ERP, MES, PLM and other industrial systems.
Read article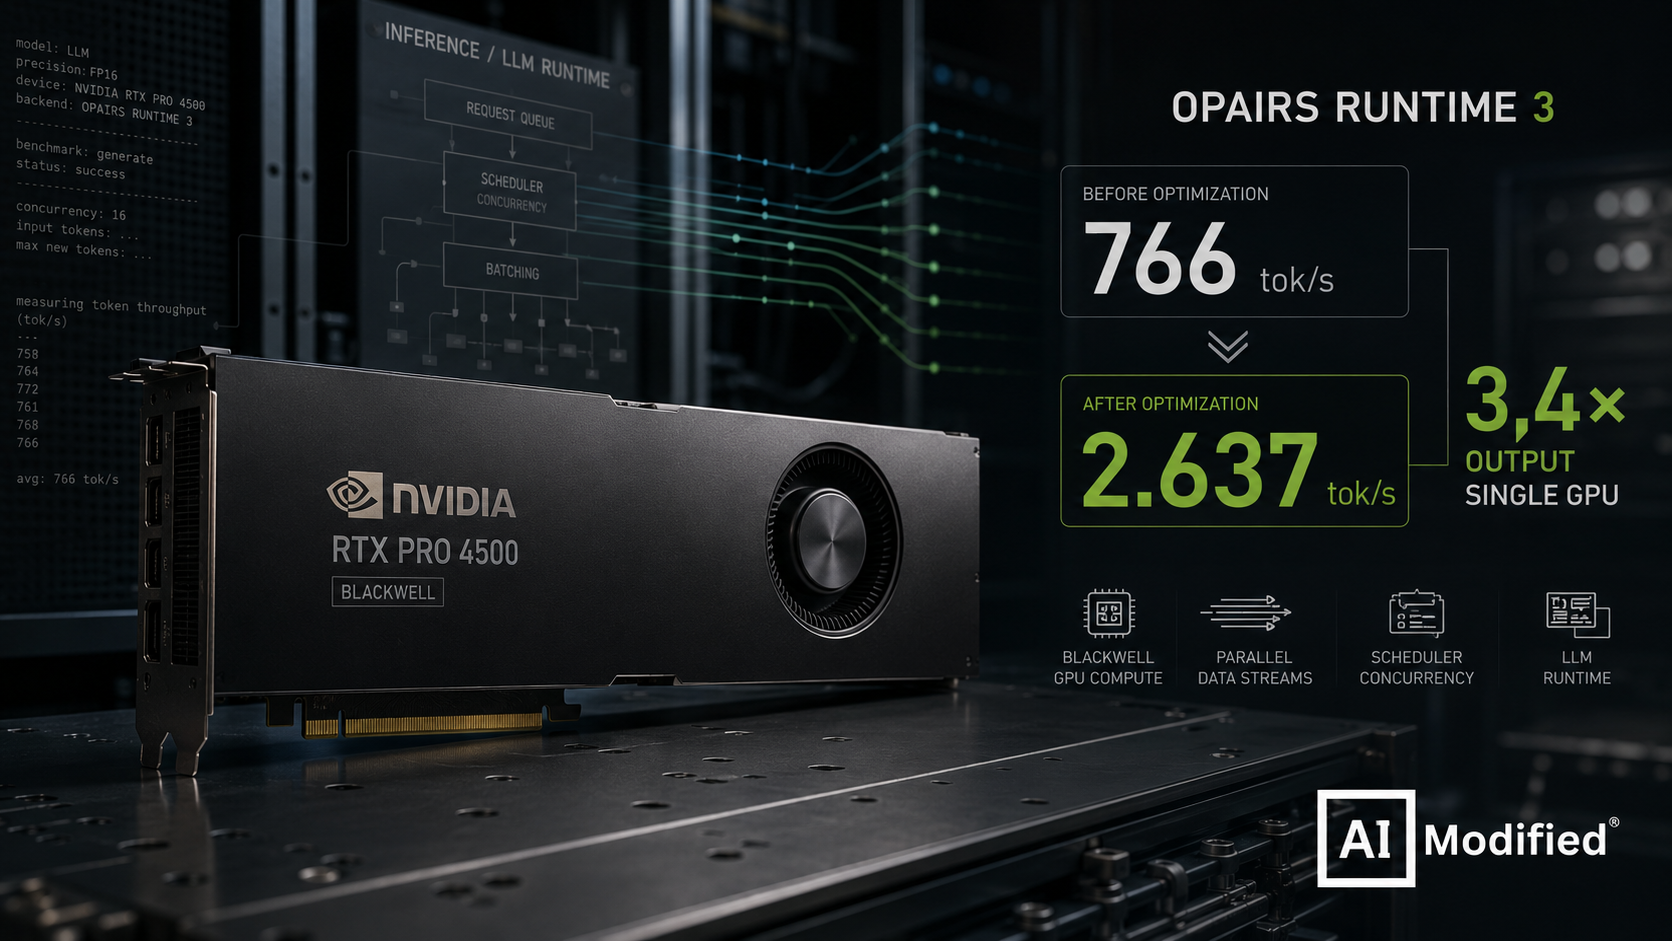
RTX PRO 4500 Blackwell: 3.4x LLM Throughput Through Runtime Optimization
Same GPU, same main model, up to 3.4x the output: OPAIRS Runtime 3 raises the throughput of GPT-OSS-20B on the RTX PRO 4500 Blackwell to up to 2,637 tokens/s. At the same time, the tests show why Qwen3.8-27B will not take over the production stack for now.
Read article