On-Premise vs Cloud AI in Production: The Comparison
This article explains in practical terms when cloud makes sense and why, for critical manufacturing processes, on-premise AI usually wins on control, availability, and compliance.
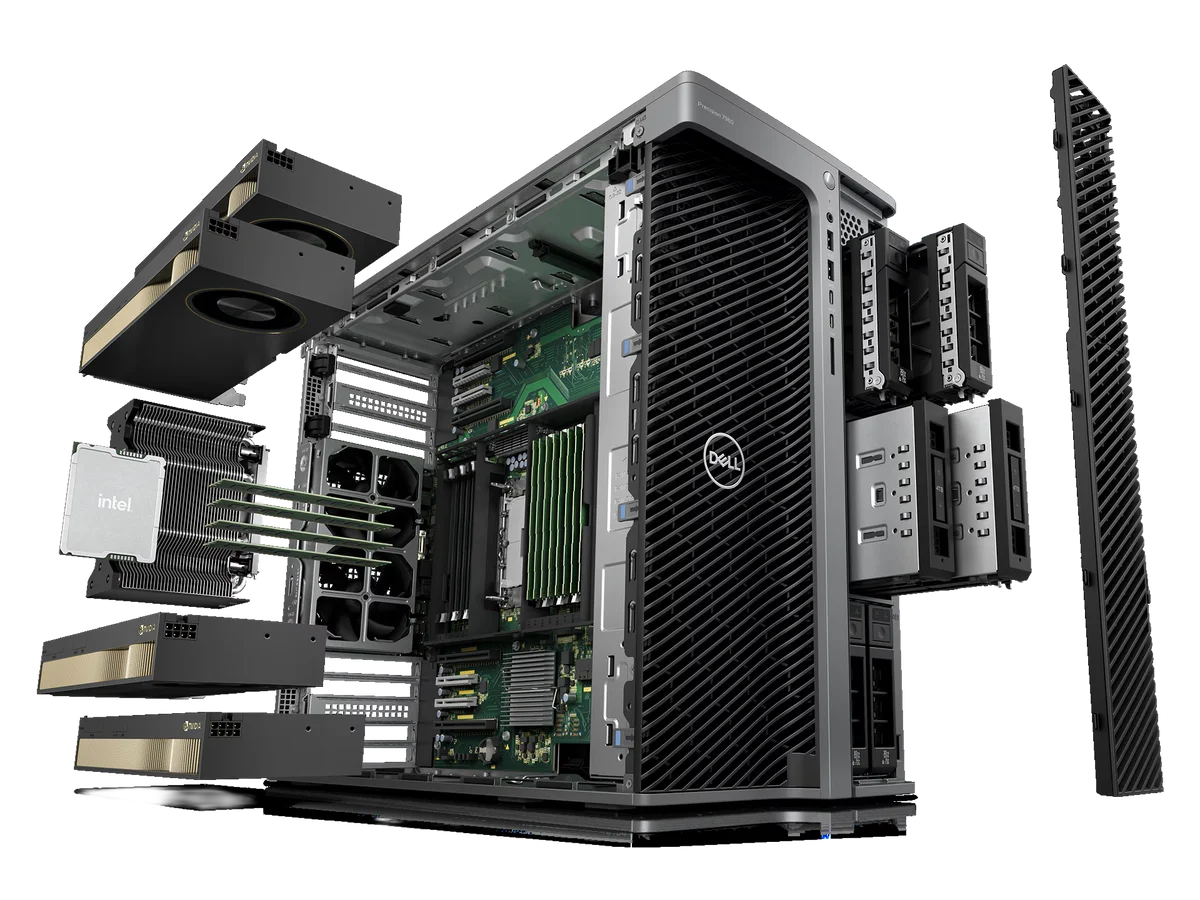
The honest answer to "Cloud or on-premise?" is: it depends on what is at stake. For analytical tasks with no data protection implications, cloud is often pragmatic. For production processes with sensitive machine data, recipes, or safety-critical control parameters, it is a structural risk – regardless of how well the service level agreement is worded.
Five criteria where on-premise wins in production
- Latency & availability: Local inference responds in milliseconds – independent of network connectivity, vendor maintenance windows, or regional outages.
- Data sovereignty: Production data, recipes, and process parameters do not leave the company. No US CLOUD Act risk, no disclosure to model providers.
- GDPR & EU AI Act: Local systems are compliant by design – no gray area when processing personal data in hybrid cloud architectures.
- Cost structure: One-time investment instead of ongoing API costs that scale with every additional use case. From ~15 users, on-premise is economically superior.
- No vendor lock-in: You stay independent of price changes, model deprecations, and vendor roadmaps.
OPAIRS is designed as a plug-and-play on-premise system: data lake, SLM inference, BI visualization, and process orchestration in one system – installed locally, with no cloud dependency and no SaaS costs. The deliberate counter-proposal to generic cloud platforms.
More insights
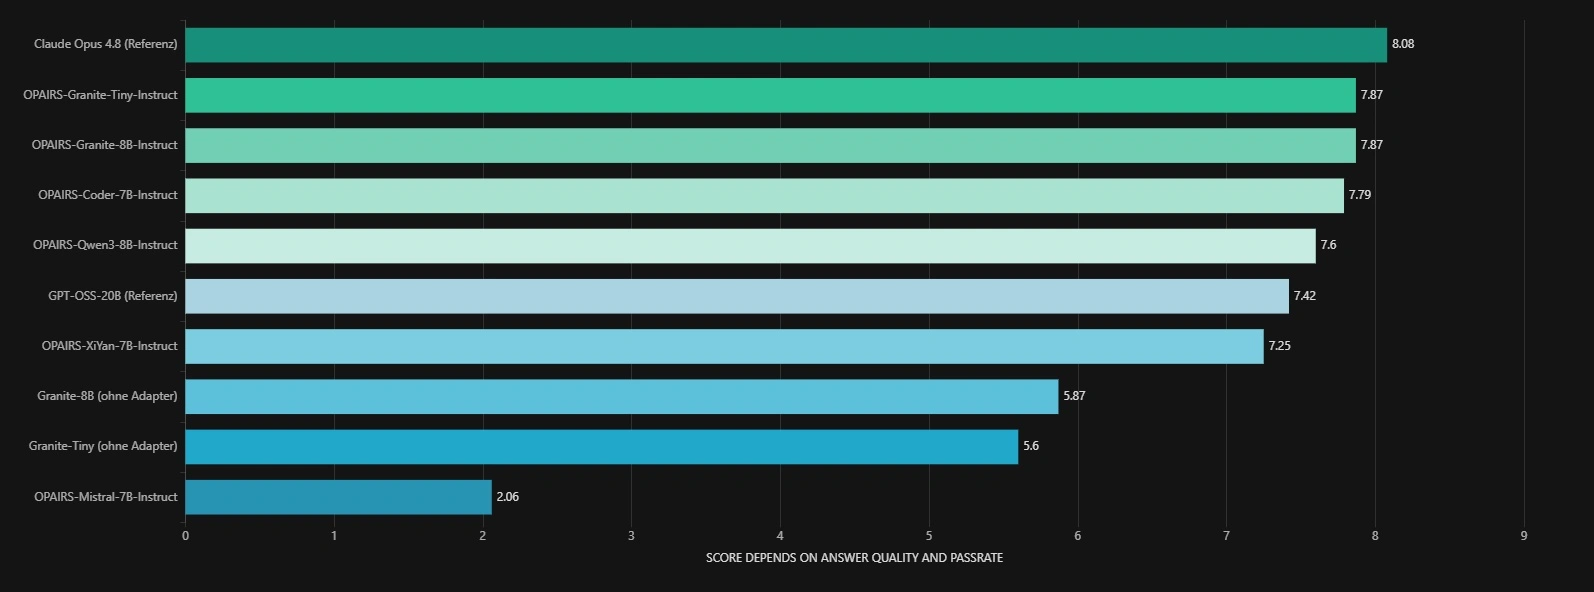
OPAIRS SQL Agent: Comparing Six LoRA Adapters for Industrial Databases
Six LoRA adapters, a 26-question catalog spanning PostgreSQL, T-SQL and Apache Iceberg databases, two external reference models: OPAIRS has systematically evaluated its SQL agent. Two Granite adapters lead the field. For production use, however, the deciding factors are not only answer quality but also speed, memory footprint, concurrency and the available context from ERP, MES, PLM and other industrial systems.
Read article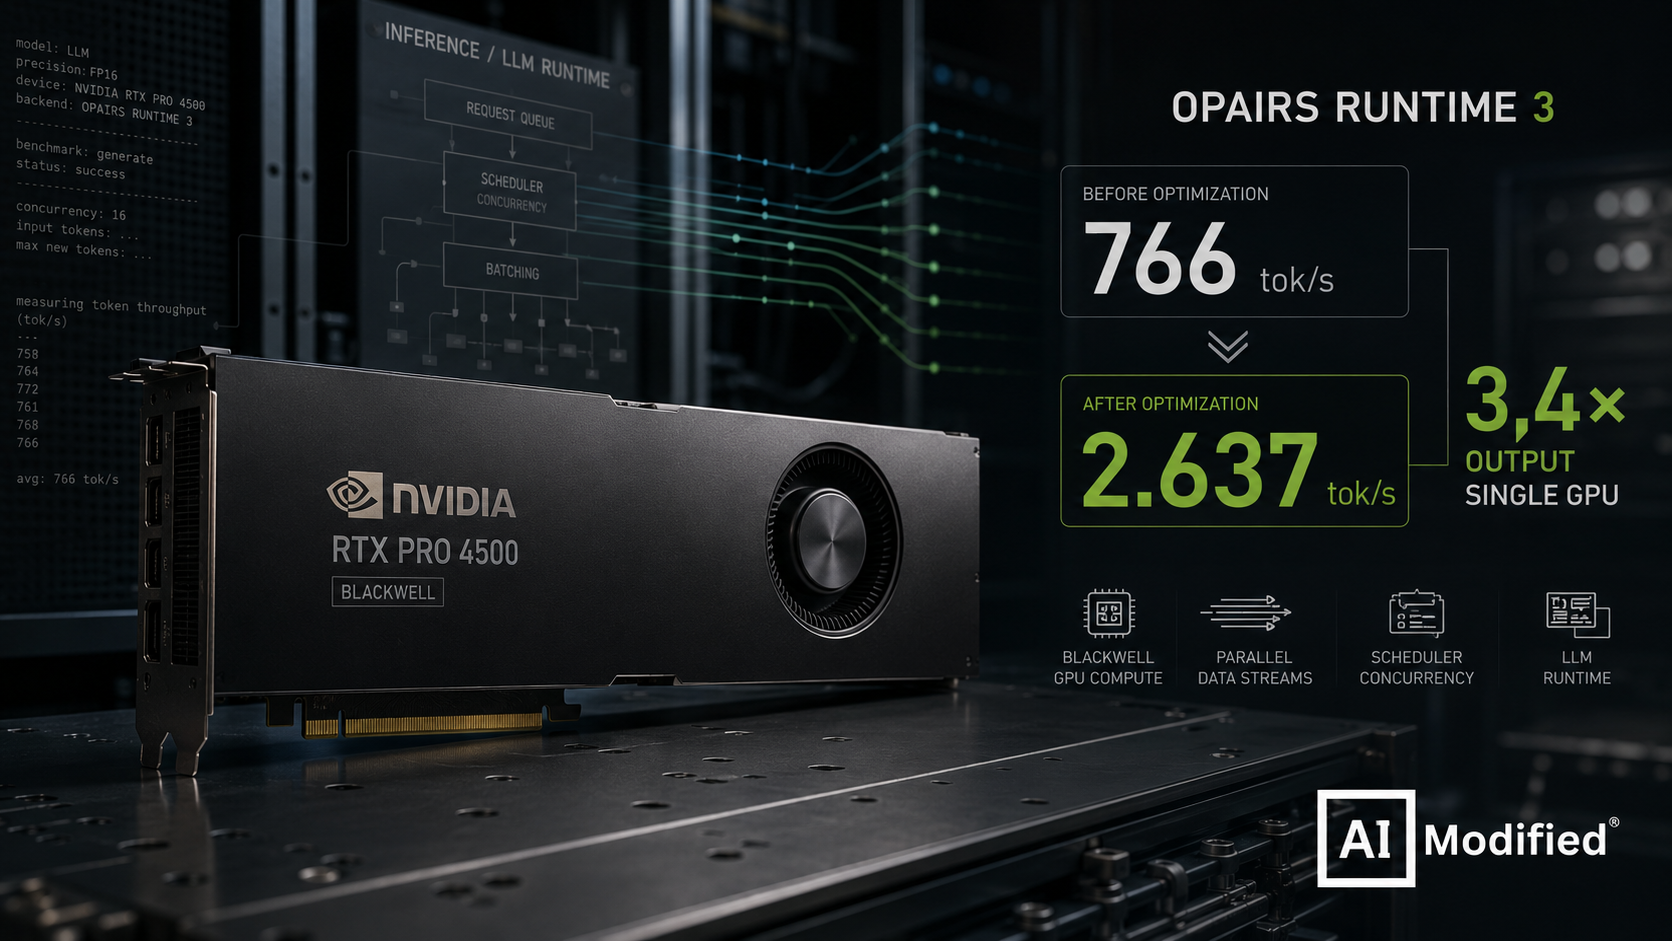
RTX PRO 4500 Blackwell: 3.4x LLM Throughput Through Runtime Optimization
Same GPU, same main model, up to 3.4x the output: OPAIRS Runtime 3 raises the throughput of GPT-OSS-20B on the RTX PRO 4500 Blackwell to up to 2,637 tokens/s. At the same time, the tests show why Qwen3.8-27B will not take over the production stack for now.
Read article